GCP Lakehouse Writer
GCP Lakehouse Writer is a Striim Platform 5.4.2 target adapter that writes initial load and change data capture (CDC) data to Apache Iceberg tables stored in Google Cloud Storage (GCS). Use this writer when you want Striim to write to the Google Cloud lakehouse path by using GCS as the data lake, GCP Managed Apache Spark (formerly Dataproc) as the compute engine, GCP Lakehouse Runtime Catalog (formerly BigLake Metastore Catalog) as the catalog, and GCS as the external staging area.
GCP Lakehouse Writer is built along the same lines as Iceberg Writer, but it is constrained to the Google Cloud lakehouse stack. The TQL adapter name is GCPLakehouseWriter. In Flow Designer, search for Google Cloud Lakehouse under Data Warehouses.
When to use GCP Lakehouse Writer
Use GCP Lakehouse Writer when you want Striim to write initial-load or CDC data to Apache Iceberg tables in Google Cloud, with GCS for table storage and external staging, GCP Managed Apache Spark for write execution, and GCP Lakehouse Runtime Catalog for table metadata. Review the catalog mode, bucket path, schema creation, and delivery semantics before you build the application because those choices affect permissions, table location, recovery behavior, and CDC processing.
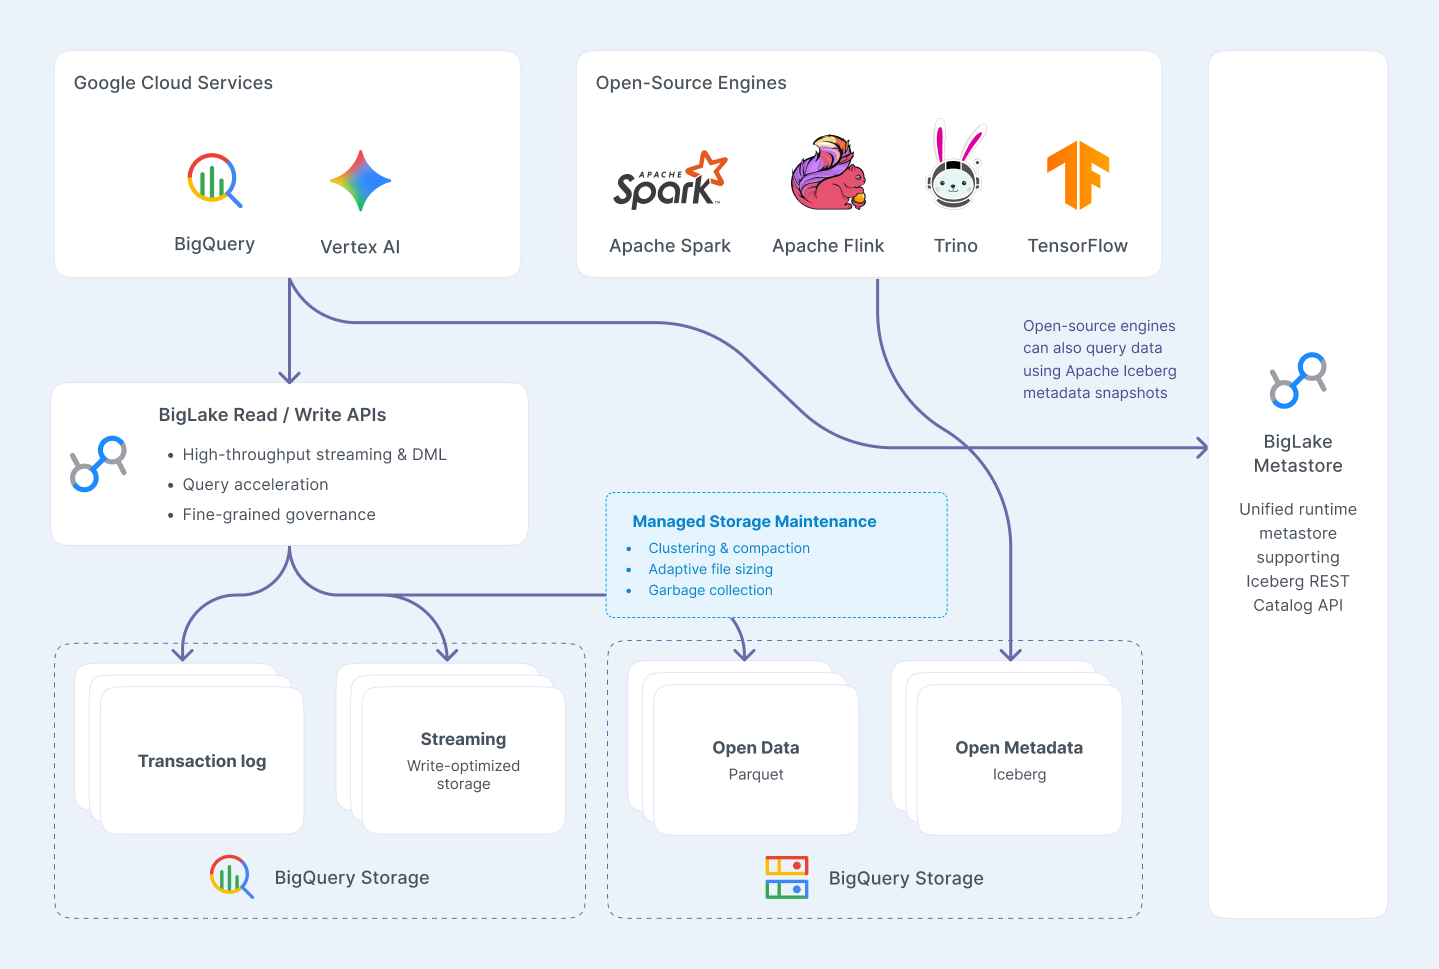
Architecture and components
Apache Iceberg separates table data, table metadata, catalog operations, and compute. GCP Lakehouse Writer uses that model to write Striim events to Iceberg tables in GCS while delegating batch execution to GCP Managed Apache Spark and catalog operations to GCP Lakehouse Runtime Catalog.
Component | GCP Lakehouse Writer support |
|---|---|
Data lake | Google Cloud Storage |
Compute engine | GCP Managed Apache Spark (formerly Dataproc), backed by Managed Service for Apache Spark |
Catalog | GCP Lakehouse Runtime Catalog (formerly BigLake Metastore Catalog) |
External stage | Google Cloud Storage |
Target adapter | GCPLakehouseWriter |
Spark compute engine
GCP Lakehouse Writer executes snapshot and CDC batches as Managed Service for Apache Spark jobs. Each batch is processed as a Spark application and split into tasks across available executors. Performance depends on worker nodes, memory, batch size, and Spark configuration.
External stage
GCP Lakehouse Writer requires a GCS external staging location. The external stage temporarily stores batch data, metadata, and execution artifacts while Spark jobs are running. The staging location must be reachable from the GCP Managed Apache Spark cluster and should be separate from the Iceberg warehouse location used for target table data.
Set the staging folder with ExternalStagingLocation. You may provide an ExternalStageConnectionProfileName for the external stage. If the data lake and external stage use the same project and authentication information, you may reuse the same GCS Connection Profile.
Authentication and data security
GCP Lakehouse Writer uses the authentication and authorization mechanisms of the Google Cloud services in the write path, including GCS, GCP Managed Apache Spark, and GCP Lakehouse Runtime Catalog. Service accounts and IAM roles authorize runtime operations.
Data stored in GCS is encrypted at rest by Google Cloud. Communication with GCS, Managed Service for Apache Spark, and GCP Lakehouse Runtime Catalog uses the secure network channels supported by the corresponding Google Cloud client libraries.